September 14th, 2026
Knowledge tables that fill in automatically, views that adapt to you…
Hi everyone,
You’re likely familiar with this situation: your teams process dozens of requests every week, your AI agents perform exceptionally well, yet when it’s time to take stock, no one really knows where things stand. The data exists, but it’s scattered across chat histories, files, and spreadsheets that no one updates anymore. So you end up manually piecing numbers together or relying on gut feeling.
That’s exactly what we wanted to solve this month, starting in the Knowledge section, specifically within your Knowledge tables. These are your business data points organized in rows and columns—leads, customer inquiries, applications, marketing campaigns—structured so your agents can read and use them to assist you. Until now, you had to fill them in manually.
Not anymore. Your agents now write to them automatically as they work. For instance, an agent qualifying leads will update your sales pipeline while you focus on other priorities. Views adjust to what you want to see, and if you need a specific dashboard, all you have to do is ask.
Your agents populate your tables on their own
An agent can now write directly into a knowledge table. Instead of just reading your data, it enriches it continuously. Every processed request, analyzed document, or conversation automatically becomes a clean row in the right columns.
This addresses a widespread issue: data generated during work often gets lost. Your agent would complete a task brilliantly, only for the details to sink into chat history. Counting, comparing, or identifying trends became nearly impossible. When making decisions, team members either guessed or spent days rebuilding numbers manually.
This workflow applies to any continuous stream of incoming tasks—whether support tickets, marketing campaigns, or job applications. Take an HR department hiring for five open roles simultaneously. As the agent screens incoming resumes, it automatically populates a table with target roles, years of experience, key skills, and availability. No manual entry required. Three weeks later, instead of opening 120 resumes to make a shortlist, the hiring manager reviews an organized database and notices that top applicants are concentrated in only two roles. The other three listings aren't weak, they're under-promoted, an insight that passive reading would never have revealed.
You only see what matters to you
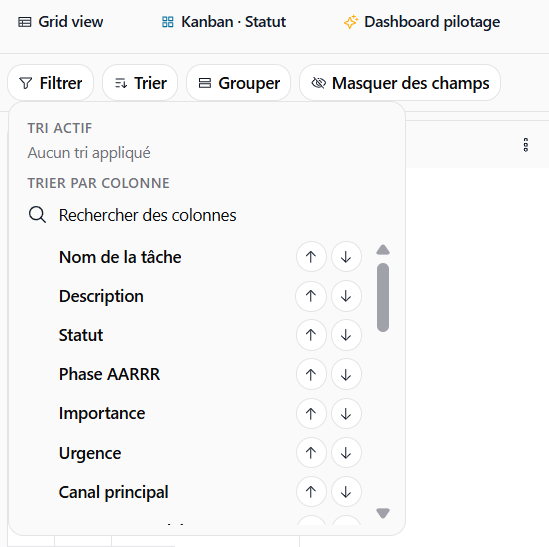
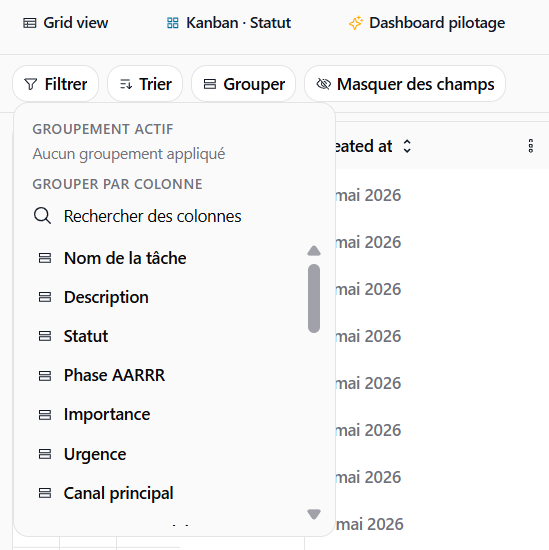
Your tables now support filters and groupings. Select your criteria, and the display reorganizes instantly. You can group rows by column—by owner, status, priority, and more—to digest information in structured sections rather than endless lists.
This grouping functionality also unlocks Kanban views. Each group becomes a column, each row a card, and progress can be reviewed at a glance rather than decoded from a hidden status column. The same table can be viewed in two ways depending on your goal: a grid when you need to compare, count, and analyze; a Kanban board when you want to monitor workflow and identify bottlenecks.
This eliminates scrolling through 800 rows to find the 12 relevant to you. More importantly, it removes the habit of exporting data to a spreadsheet “to sort in peace”, which inevitably created outdated duplicate files.
Consider a customer support manager tracking 800 open tickets from the current quarter. Instead of reviewing everything, they filter by unresolved tickets and group them by issue type. Within seconds, a trend emerges: one-third of complaints stem from a single product line. Volume isn't the core issue—the product feature is, requiring engineering intervention rather than customer support fixes. The same approach benefits executive management: a board filtering by the current quarter and grouping by business unit enters meetings with a shared single source of truth, rather than five disjointed reports.
Dynamic views generate your ideal interface
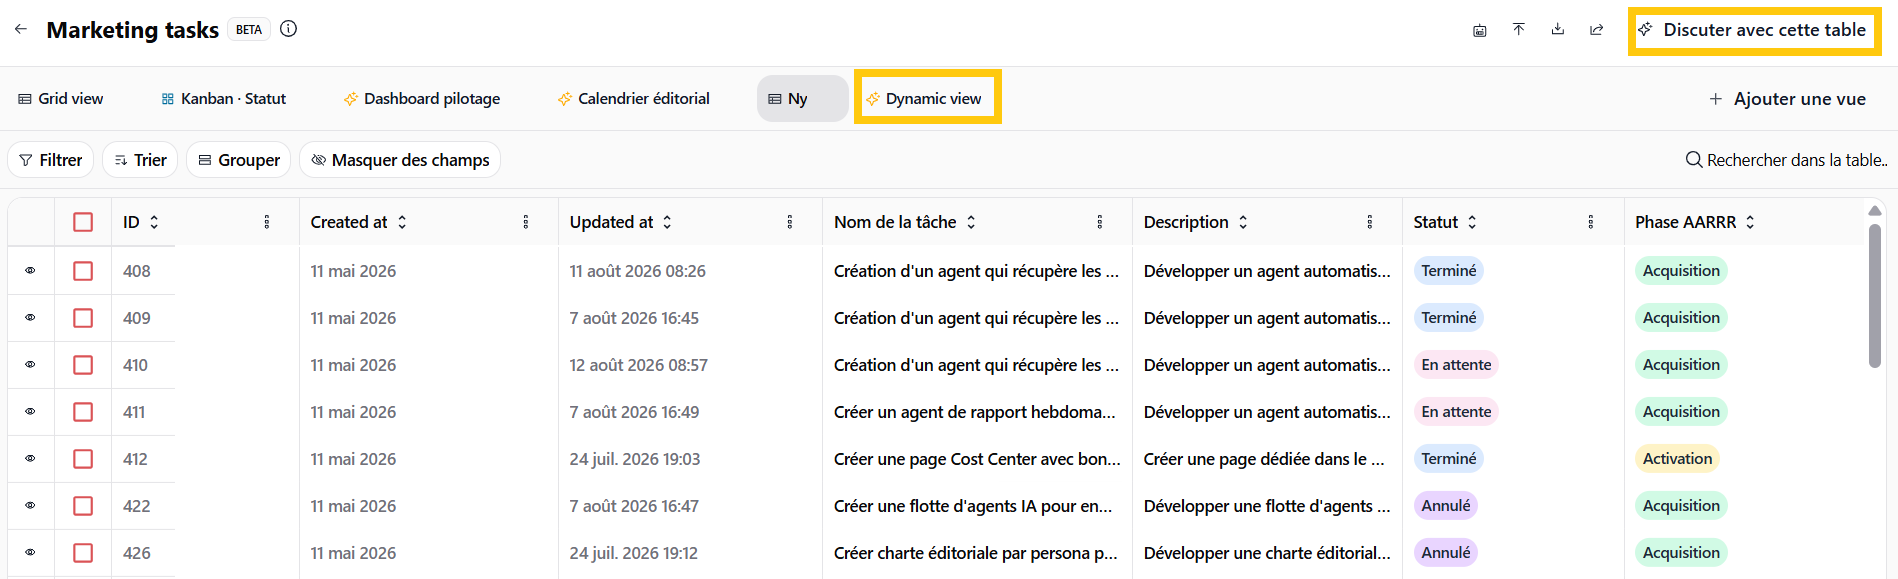
Directly from the Knowledge section chat, you can request the exact view you need. Describe what you want to track, and Swiftask generates a tailored interface: a dashboard, a stage-by-stage pipeline, or an executive summary view. You don't even need to configure an agent beforehand—a simple sentence in plain language is enough.
This removes friction and turnaround time. Previously, custom reporting meant submitting a ticket to the data team, waiting for delivery, and often receiving a report for a need that had already evolved. Now, you can test a visualization approach in minutes and iterate immediately if needed.
A marketing director allocating year-end budgets can simply request a view crossing acquisition cost, conversions, and ROI by channel over the last six months. She receives a clean dashboard, identifies that two channels consume most of the budget while generating a third of results, and reallocates accordingly. The same mechanism helps track organizational AI usage: a view crossing session counts, error rates, and token consumption by agent highlights which assistants are costly relative to performance, or failing due to vague instructions. You know what to optimize first and have the data to support it.
Your agents confirm details before acting
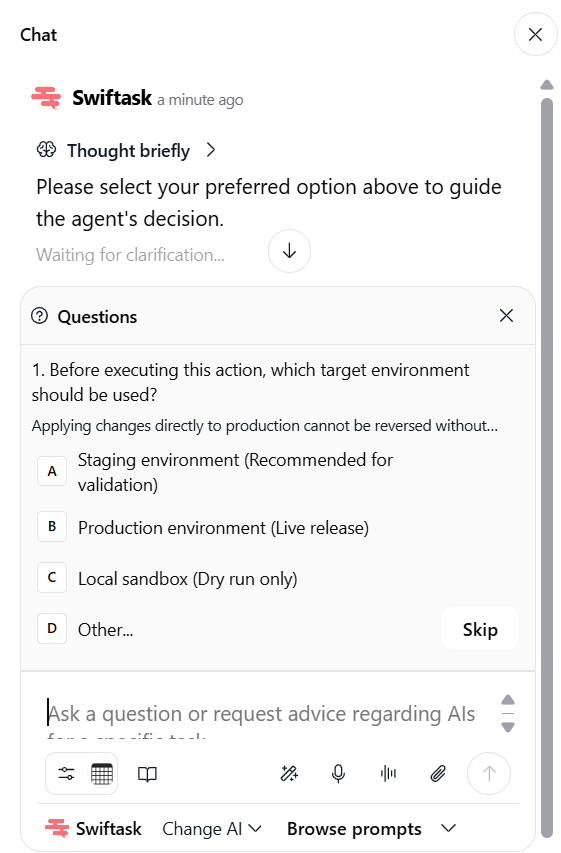
When a request could be interpreted in multiple ways, your agent no longer guesses. It pauses, prompts you through a clear interface, and offers defined options. Once you select an option, it proceeds with the correct instruction.
The immediate benefit is clear for sensitive operations : sending external communications, modifying database entries, or initiating spending. However, the secondary benefit is equally valuable: team members don't need to be expert prompt engineers to get precise results. The provided options serve as clear guardrails, helping new users learn as they go.
For example, an HR agent tasked with following up on pending candidates will ask whether to target candidates waiting over 15 days or over a month, and whether to include all roles or only open ones. A 10-second confirmation prevents misdirected emails and hours of manual corrections.
Together, these four capabilities create a unified workflow: agents generate your data, filters isolate what matters, dynamic views inform your decisions, and agents confirm intent before taking action.
To explore these features, head to Knowledge ➔ Knowledge Tables in your workspace.